

In “✪ “Vetted by X” Is the New Michelin Star - #78” I framed the expert as someone who verifies claims, who checks things. In this issue I explore the structural consequence: once you verify with visible methodology, you become a trust node that agents route through. The verifier checks claims. The trust node is what agents route through.
Agents Now Outnumber You Online
This issue explores what they're looking for, how that changes the expert's job, and where to make your judgment visible.
The majority of visitors to your site are now machines. As of early 2026, bots account for 57.4% of all web requests, according to Cloudflare’s network data. Imperva’s 2025 Bad Bot Report confirmed the threshold was first crossed in 2024. Agentic AI traffic specifically, the kind generated by systems that research, compare, and synthesize on behalf of a human who never touches the page, grew approximately 8,000% in 2025 alone.
This issue is about what that shift means for you as an independent expert, what these agents are actually looking for, how that differs from what a human reader needs, and what you'd do differently if you took it seriously starting today.
In this issue:
1. The Traffic Stats, and Why They Matter
The shift was projected to happen around 2027. Cloudflare CEO Matthew Prince said in early 2026 that agentic traffic had eclipsed human traffic a year early, and he didn’t sound pleased. Automated internet traffic grew 23.5% year-over-year in 2025, while human traffic grew 3.1%, roughly 8 times faster. AI-driven traffic specifically jumped 187% in 2025.
The new category driving this isn’t traditional SEO crawlers. It’s agentic traffic: AI systems browsing the web on behalf of a user who submitted a question or a task. When someone asks an AI assistant to find expert opinion on a topic, evaluate tools, or summarize the research landscape, an agent goes out and reads dozens of pages before synthesizing an answer. Your page may soon receive ten machine visits for every one human who actually reads it.
If you’ve noticed changes in your traffic patterns, referral sources, or engagement rates this year, this is part of what’s happening.
2. What an Agent Actually Does On Your Page
A human reader scans your headline, reads a few paragraphs, decides whether to trust you, and either stays or leaves. The essay format, narrative arc, buildup, and conclusion are designed for that experience.
An agent does something different. It interrogates the page for structured, citable claims. Who made this claim? When was it last updated? What evidence sits underneath it? Does this match what other reliable sources say?
Researchers at Princeton and Georgia Tech analyzed over 10,000 AI search queries and found that content incorporating authoritative citations, direct quotations, and verifiable statistics achieved 30-40% higher visibility in generative engine responses.
The agent rewards the content that shows its work. Narrative prose gets mined for one quotable sentence and the rest is ignored.
This is what the emerging field of Generative Engine Optimization (GEO) documents. The content that gets cited by AI systems isn’t the most eloquent. It’s the most legible to a machine evaluating trust signals: a clear claim, the evidence under it, a named author, a date.
3. Value Moves To the Verifier
In issue #78 of TRUST-able, I wrote about the emerging role of the expert as the verifier:

Someone who checks claims, assesses sources, and builds a track record of being right. That’s the foundation.
What I want to show you here is the next level up.
Verifying is an act. What I’m describing now is an architecture. When your verified work is structured so that an agent can retrieve it, attribute it, and route other people’s questions through it, you’ve become something more than a verifier.
You’ve become a trust node.
The 2026 academic paper “Engineering the RAG Stack” (arXiv:2601.05264) is direct about why this matters: “At every step, the bottleneck is the same: the quality, freshness, and trustworthiness of what gets retrieved.”
RAG - retrieval-augmented generation - is the dominant architecture powering AI research agents. It’s built around source attribution. The agent finds your content, evaluates whether it can be cited with confidence, and either uses you or moves on.
Structured, attributed content at a stable URL gets retrieved. The anonymous, undated blog post gets skipped.
A parallel paper from 2025 (arXiv:2510.12859) describes the broader shift: “In a world of machine-generated outputs, human judgment migrates from production to verification, curation, and contextualization.”
The marginal cost of generating content is approaching zero. What’s scarce is the human judgment that tells you which part of it to trust.
4. From Verifier to Trust Node
The verifier checks claims. The trust node is what agents route through. That’s quite a difference.
Checking a claim is a moment. Being a trust node is a structure. An agent that finds you reliable on topic X will return to you on topic X, cite you across multiple queries, and contribute to a machine-resolvable reputation that grows with each interaction.
The paper “Architecting Trust in Artificial Epistemic Agents” (arXiv:2603.02960, 2026) addresses this directly: what structural properties make a source trustworthy enough for an agent to delegate to?
These are the ones:
Consistency of position across time.
Clear methodology.
Named authorship.
Stable URL.
Track record of accuracy.
Your mission as an expert has always been to become worth trusting. The agent era adds a layer: to be structured enough for a machine to verify that trust, and to return to you instead of someone cheaper and faster.
Don't just write to be read. Structure your work so it can also be verified, cited and returned to.
5. Five Things To Do Differently Starting Now
a) Publish atomic, self-contained claim units instead of burying insight in prose
Your sharpest judgment probably sits four paragraphs deep, surrounded by context that explains it. When an agent lifts that sentence, it loses the support around it. Write your key claims as standalone units: the claim, the evidence under it, the conditions where it holds, and the source. The essay can still wrap them for human readers, but each unit should survive on its own when extracted.
b) Make your vetting visible and dated
An agent asks “Can I trust this?” before it uses anything. Attach the trail: what you checked, what you found, your confidence level, the date you last verified. Most people publish conclusions with no provenance. The attached methodology is your strongest edge, and almost no one else will do it. A piece that shows “I looked at X, Y, and Z sources, rejected W because of these reasons, and concluded this on this date” is structurally different from an opinion piece that reaches the same conclusion.
c) Maintain a few living references (knowledge infrastructures) instead of shipping only disposable posts
A static article decays, and a RAG system notices the staleness. A dated, versioned reference at a stable URL with a visible “last verified” becomes the canonical source agents return to. Shifting even 20% of your effort from publishing new things to maintaining and updating a handful of authoritative ones will compound faster than you expect. Maintenance is a trust signal.
d) Connect your claims, don’t just stack them
Agents traverse relationships. Link your claims to their sources, your terms to clear definitions, your positions to the specific conditions where they apply. Use explicit relationship labels where you can: “this supports X,” “this contradicts Y,” “this is an example of Z.” A connected, consistent body of work lets an agent model you as a coherent authority rather than a stream of disconnected opinions.
e) Build a consistent, resolvable identity across platforms
An agent needs to know who is making a claim and whether that source has been reliable elsewhere on the web. Your name, your positions, and your credentials should be consistent and corroborated across the surfaces where you publish. A public track record of being right, anchored to your name, at stable URLs, is the early version of what reputation monetization projects are trying to formalize.
Here’s some complementary supporting advice from SUSO’s Head of Content, Jamie Stanley:
Query fan-out:
Offer high-value content for related follow-up questions to signal real topical authority.Add citations:
Be a hub that interprets other people’s ideas. AI likes to validate an author’s sources before it validates the author himself.Name & link authors:
Provide and link author credentials to their online professional profiles.
6. Platform Guide: Where To Make Your Judgment Visible
To become a trusted primary source, in your specific sector, it matters where you publish your content. Especially because AI agents are always on the lookout for signs and proof that you’re trustable, reliable, verifiable and stable, and if the platform you use, corroborates that, so much the better.
But not every platform exposes your judgment, your identity and your methodology equally well to AI agents.
Some offer all the critical elements that agents need to verify your authority and trustworthiness, while others don’t or do it only in part.
Here are the four critical elements I would be looking for - when choosing a publishing outlet - to make sure that they will match the structure and format that search agents expect:
Public & crawlable
Visible to agents and search bots on the open web, no login required.Judgment visible
Your annotation/analysis stays with the content, not just a URLNamed attribution
Your name and identity are clearly and durably attached to the workAuthority accrues to you
Your reputation gets built, not the one of the platform
To assess which ones are most relevant for independent experts, journalists and advisors, I identified all platforms I would consider today for sharing my work, and verified how much each one matched the four critical requirements listed above.
These are (23):
Substack, Medium, your own website, Glasp, Sublime, LinkedIN, Scoop.it, Are.na, Notion public pages, Github, Reddit, X.com, Cosmos, Start.me, eLink, Pinterest, Trello, Facebook, Instagram, TikTok, Wakelet, the new ZEEF, a personal public knowledge base or second brain.
Here the results of my analysis of 20+ publishing platforms and social media venues and their aptness in being the ideal “trusted outlet” on which to publish.
Scoring criteria: (0-2 for each criteria, max total score 8)
Public & crawlable
Is it public and crawlable, or locked inside an app?Judgment visible
Does it carry your visible judgment, or just a saved link?Named attribution
Does it attribute durably to you as a named source?Authority accrues to you
Who accrues the authority - you or the platform?
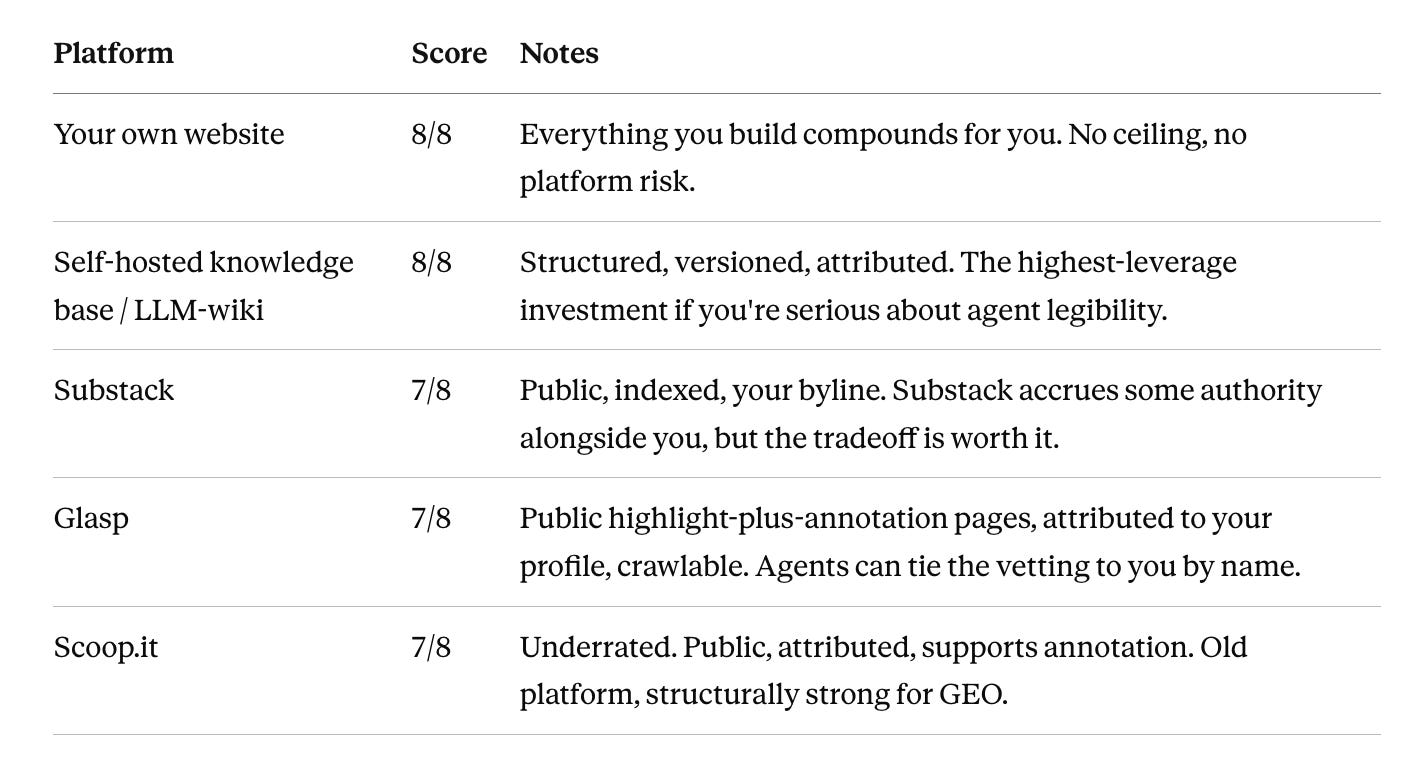
Tier 1 — Build here (Score: 7-8 / 8)
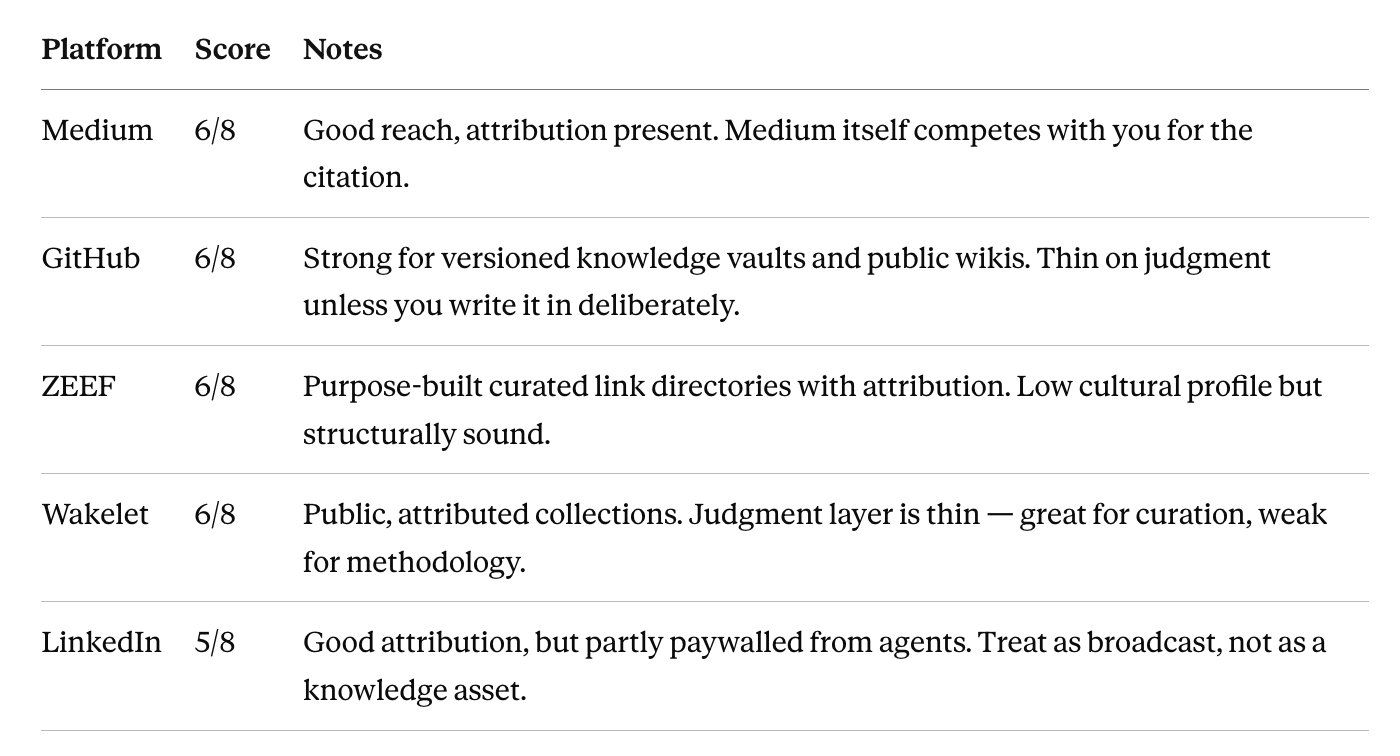
Tier 2 — Use with intention (Score: 5-6 / 8)
Tier 3 — Practice ground, not proof layer (Score: 3-4 / 8)
Are.na (4/8)
Notion public pages (4/8)
Reddit (3/8)
X.com (3/8)
Cosmos (3/8)
Start.me (3/8)
eLink (3/8)
These are useful for thinking, connecting, and finding your angle. Publish the vetted output to Tier 1 surfaces.
Tier 4 — Distribution only, no agent legibility (Score: 0-2 / 8)
Sublime (2/8)
Pinterest (2/8)
Trello (2/8)
Facebook (2/8)
Instagram (2/8)
TikTok (2/8)
Use these if your human audience is there. Understand they contribute nothing to your machine-readable authority.
Key Insights from the Scoring:
a) The platforms that score 7-8 are all public, attributed, and maintain a judgment layer.
b) The platforms that score 0-3 are either closed to agents or strip your identity from the content.
c) The middle tier (4-6) is where most experts spend most of their time.
Recommendation: Use the platforms that score 0-3 and the middle tier ones as practice and training grounds, where you capture, connect, and form your judgment.
Then publish the vetted, annotated output to a surface you own and maintain, where it’s crawlable, attributed to you, and stable. Doing so converts your private curation into an agent-legible asset that compounds for you instead of for the platform.
Beware: a large, tidy pile of unannotated saves feels like curation but it is nearly worthless to an agent. The judgment you attach, why this, what’s strong, what to discard is the true valuable asset. Without it, you’re positively feeding someone else’s data.
What Happens To Standard Articles?
a) Articles are how a human meets you.
b) Structured, maintained, vetted knowledge is how an agent decides to trust you and return.
You don’t have to choose one over the other. The essay can still be the surface humans read. What needs to change is what you offer next to it.
7. Claims / Sources
Claim 1: Agents Already Outnumber Human Web Traffic
As of early 2026, bots account for 57.4% of all web requests (Cloudflare). Imperva confirmed the threshold was first crossed in 2024 at 51%. Agentic AI traffic — the kind that acts on behalf of a human who never touches the page — grew approximately 8,000% in 2025 alone.
Agentic traffic explodes: Tom’s Hardware / Cloudflare CEO quote (March 2026): Bot requests now represent 57.4% of all HTTP traffic, versus 42.6% from humans. Cloudflare CEO Matthew Prince noted agentic traffic eclipsed human traffic ahead of schedule. [Source: Tom’s Hardware / Cloudflare, March 2026; blog.cloudflare.com - Radar 2025 Year in Review]
AI crawlers specifically: AI crawlers now account for approximately 8.7% of all HTML request traffic, up from near-zero two years ago. [Source: Cloudflare Radar 2025 Year in Review]
Growth rate: Automated internet traffic grew 23.5% year-over-year in 2025, vs. 3.1% for human traffic — roughly 8x faster. AI-driven traffic jumped 187% during 2025. [Source: Human Security State of AI Traffic report, NBC News (March 2026)]
Agentic AI specifically: Traffic from agentic AI (systems that act on behalf of humans, not just crawl for indexes) grew ~8,000% in 2025. [Source: CNBC, March 2026]
Imperva Bad Bot Report 2025: Automated traffic crossed the 50% threshold in 2024, reaching 51% of all global web traffic — the first time in a decade bots exceeded humans. [Source: Imperva Bad Bot Report 2025, via cybersecuritynews.com]
Claim 2: Value Shifts from Producing to Vetting, Verifying, Organizing
A study by Princeton and Georgia Tech researchers analyzing over 10,000 AI search queries found that content with authoritative citations and verifiable statistics achieved 30-40% higher visibility in generative engine results. Agents aren’t reading your personal story. They’re mining for citable units.
Princeton / Georgia Tech study (analyzed 10,000+ AI search queries): Content incorporating authoritative citations, direct quotations, and verifiable statistics achieved 30-40% higher visibility in generative engine responses. The implication: the agent rewards the curator who shows their work, not the writer who buries it. [Source: GEO research, referenced in seotuners.com, frase.io, multiple GEO guides 2025-2026]
Experian / agency survey: Nearly 9 in 10 agencies identify curation as a key driver of future media buying value; 70% of those already using curated approaches report tangible ROI benefits. [Source: Experian press release 2025, experianplc.com]
Academic framing: An arxiv paper “Three Lenses on the AI Revolution: Risk, Transformation, Continuity” describes the transition: “In a world of machine-generated outputs, human judgment migrates from production to verification, curation, and contextualization. This represents a fundamental transformation paralleling industrial-era shifts.” The paper identifies a “verification-first stance” emerging in how content is consumed — readers and agents alike expect provenance, citations, uncertainty markers.
“The Verification Crisis: Expert Perceptions of GenAI Disinformation and the Case for Reproducible Provenance”: arXiv paper on GenAI disinformation documents how AI “exponentially increases content generation capacity, overwhelming human verification systems through sheer volume.” The bottleneck moves from production to verification.
Claim 3: The Expert Becomes a Trust Node Agents Route Through
RAG - the retrieval architecture powering most AI research agents - is built around source attribution. The 2026 paper “Engineering the RAG Stack” (arXiv:2601.05264) is direct: “At every step, the bottleneck is the same: the quality, freshness, and trustworthiness of what gets retrieved.” Structured, attributed content at a stable URL is what gets retrieved. The anonymous blog post gets strip-mined for one sentence and discarded.
RAG architecture: Retrieval-Augmented Generation (RAG), the dominant architecture behind AI agents that research and answer questions, is built on source retrieval and attribution. AWS, NVIDIA, and Databricks all document that RAG gives agents “sources to cite, like footnotes in a research paper.” The key trust signal is structured, attributed, verifiable content at a stable URL. [Sources: AWS What is RAG; NVIDIA RAG blog; Databricks RAG glossary]
“Engineering the RAG Stack”(arXiv:2601.05264) - “At every step, the bottleneck is the same: the quality, freshness, and trustworthiness of what gets retrieved.” The paper establishes that provenance is the primary trust mechanism — if a source can be traced and tested, it carries weight; if it can’t, it’s discarded.
“From Fluent to Verifiable” (arXiv:2602.13855, 2026): Proposes claim-level auditability for deep research agents, the framework where agents evaluate whether a source can be cited with confidence at the individual claim level.
Architecting Trust in Artificial Epistemic Agents (arXiv:2603.02960, 2026): Addresses how agents decide which human or institutional sources to route knowledge through, and what structural properties make a source trustworthy to a machine.
GEO (Generative Engine Optimization): The emerging practice of structuring content so AI systems can extract precise, verifiable answers and cite your brand inside synthesized results. The core principle: clear claim + evidence + date + named author = citable unit. [Source: GEO research, referenced in seotuners.com, frase.io, multiple GEO guides 2025-2026]
8. Paradata
Intent / Why: I wrote this article / report to highlight one of the most underrated changes happening today and relating to the editorial work of experts, consultants, advisors and journalists online. As human search is gradually replaced by AI agents searching for us, it is vital to become aware of - under such circumstances - is necessary to do, to make sure that such new type of visitors to our content will find not only what they’re looking for, but also clear signs that we are a trusted, reliable and stable re-source for that kind of information.
Process: I unexpectedly run into the news that most of the web traffic will soon be almost completely agentic, by reading the “AI Search Manifesto” by The State of Brand. It is an article with no named author, but it has a lot of useful and verified references. I then further investigated the topic by asking both ChatGPT and Claude to do some deeper research into it. When I had enough information confirming the traffic shift from human to agentic, I moved the research in the direction of understanding how would that specifically impact experts online, in their approach to building visibility and authority in their sector. That’s how I gradually expanded the focus to include two more key shifts taking place (value shifting from content production to vetting / verifying - and experts who verify, curate and contextualize information gradually becoming trusted sources that AI systems learn to return to repeatedly.
So I consolidated first my three key claims, and then worked backwards to identify a title that synthesized and reflected those findings, and then worked to develop the content to describe those facts.
At this point I used both ChatGPT and Claude, to analyze all possible actions-solutions that an expert could take to protect its mission while these changes are taking place and identified five that best fit my existing knowledge, experience and intuition.
It came to me at this point, due to my interest and experience with relevant tools and platforms used by experts, to analyze all the possible “surfaces” where structured, verifiable content, should be ideally published to meet these key changes.
I assembled all of these sections, and evaluated their possible best sequence multiple times. I decided to separate the guide to which platforms to use to a paywalled section (which I almost never use) to lighten the main content and to give an opportunity to die-hard readers that really enjoy this type of information, to demonstrate their appreciation and support tangibly.
Time: Research of key changes: 3 hrs. Draft analysis of possible consequences: 1.5 hrs. Identify possible solutions and recommendations: 1 hr. Overall outline draft and writing: 2 hrs. Supporting sources identify and verify: 1 hr. Platform guide analysis and preparation: 1.5 hrs. Formatting: 1 hr. Cover design: 1 hr. Total apx time: 12 hrs.
Tools:
ChatGPT, Claude for research, analysis, draft outlining, content verification.
WUWT for rapid in-depth analysis and primary sources verification.
Cover image: Chief air traffic controller - Concept & Design by Robin Good executed by ChatGPT Image 2
Best Platforms To Satisfy AI Agents Looking for Trustable, Verifiable Content
The act of curating with judgment matters more than ever.
Where you do it decides whether an agent ever sees it, or whether you're just feeding someone else's data moat.
Platforms analyzed (23): Substack, Medium, your own website, Glasp, Sublime, LinkedIN, Scoop.it, Are.na, Notion public pages, Github, Reddit, X.com, Cosmos, Start.me, eLink, Pinterest, Trello, Facebook, Instagram, TikTok, Wakelet, the new ZEEF, a personal public knowledge base or second brain.
Scoring criteria: (0-2 for each criteria, max total score 8)
Public & crawlable
Is it public and crawlable, or locked inside an app?Judgment visible
Does it carry your visible judgment, or just a saved link?Named attribution
Does it attribute durably to you as a named source?Authority accrues to you
Who accrues the authority - you or the platform?
Tier 1 — Build here (Score: 7-8 / 8)
Tier 2 — Use with intention (Score: 5-6 / 8)
Tier 3 — Practice ground, not proof layer (Score: 3-4 / 8)
Are.na (4/8)
Notion public pages (4/8)
Reddit (3/8)
X.com (3/8)
Cosmos (3/8)
Start.me (3/8)
eLink (3/8)
These are useful for thinking, connecting, and finding your angle. Publish the vetted output to Tier 1 surfaces.
Tier 4 — Distribution only, no agent legibility (Score: 0-2 / 8)
Sublime (2/8)
Pinterest (2/8)
Trello (2/8)
Facebook (2/8)
Instagram (2/8)
TikTok (2/8)
Use these if your human audience is there. Understand they contribute nothing to your machine-readable authority.
Key Insights from the Scoring:
a) The platforms that score 7-8 are all public, attributed, and maintain a judgment layer.
b) The platforms that score 0-3 are either closed to agents or strip your identity from the content.
c) The middle tier (4-6) is where most experts spend most of their time.
Recommendation: Use the platforms that score 0-3 and the middle tier ones as practice and training grounds, where you capture, connect, and form your judgment.
Then publish the vetted, annotated output to a surface you own and maintain, where it's crawlable, attributed to you, and stable. Doing so converts your private curation into an agent-legible asset that compounds for you instead of for the platform.
Beware: a large, tidy pile of unannotated saves feels like curation but it is nearly worthless to an agent. The judgment you attach, why this, what’s strong, what to discard is the true valuable asset. Without it, you’re positively feeding someone else’s data.
What Happens To Standard Articles?
a) Articles are how a human meets you.
b) Structured, maintained, vetted knowledge is how an agent decides to trust you and return.
You don’t have to choose one over the other. The essay can still be the surface humans read. What needs to change is what you offer next to it.
Learn More About Curation
I help experts and consultants who are building a new online career gain the authority, credibility, and visibility they initially lack.
I do this by teaching them how to become top trusted curators in their area of expertise.
For this purpose I’ve created a focused 55-minute video workshop that walks you through:
Why curated content formats are so useful for building credibility and authority
When to use them and what requirements they have
An updated list of real-world examples of curated formats at work
The specific tools you need to curate
The actual key steps that transform researching and writing into curation
The 11 typical mistakes novice curators make
Follow a path with a heart.
The time is now.

From Koh Samui (TH)
Robin Good