

The Curator is a knowledge base that gets smarter with every source you add by compiling what you know into a structured, growing intelligence. What the second brain was always trying to be.
Authority in a niche requires the ability to see what others don’t, to connect what others see as separate entities, to hold the field’s multiple views and contradictions in view while making sense of them.
This kind of depth can be created through a rule-based system for accumulating and connecting the things you’ve read. And the expert who builds such a curated knowledge base ends up with something quite unique: a compiled intelligence. A living, structured, growing model of their field, built from their own personal choices.
Doing this, changes how the expert writes.
How?
An expert with this system doesn’t need to return to research new sources for every article. The synthesis is already there, cross-referenced, visible. The extra depth that readers sense in the expert published work has now visible strong roots.
It also changes how the expert answers questions too.
Being specific and having the ability to cross-reference with clarity different ideas, sources and concepts, signals genuine domain mastery and builds reader trust over time, because those abilities can come only from someone who deeply knows the stuff he is talking about.
Now that AI can generate such professional-sounding content for anyone, readers can’t always name why one expert feels authoritative and another one feels polished but shallow. But they can sense the difference. A compiled intelligent knowledge base, one that grows alongside the expert who nourishes and takes care of it, is a tool for consolidating that difference.
From Second Brains To Sense-Making Systems
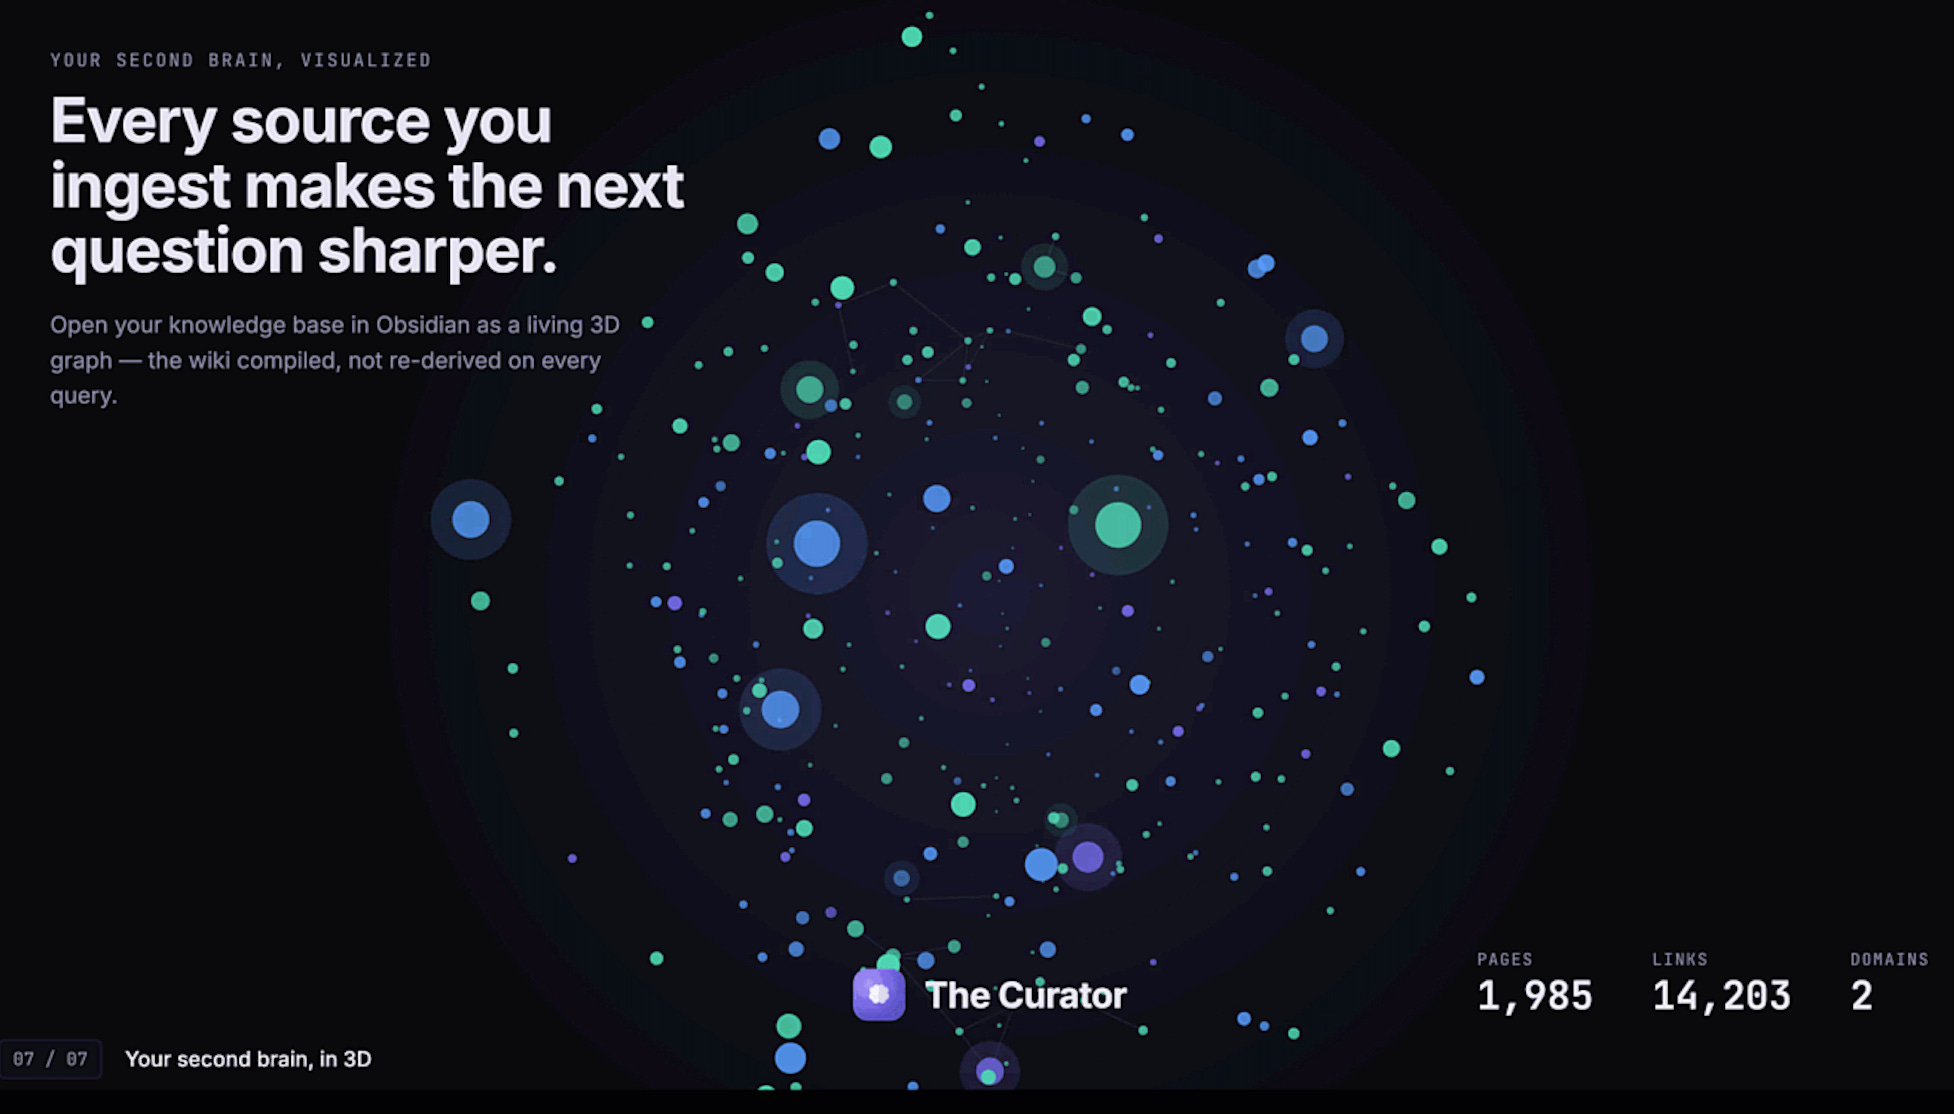
For three or four years, the second brain movement had a good run. Tiago Forte’s book. Notion databases. Roam Research graphs. Obsidian vaults stitched together with backlinks.
The underlying idea was indeed compelling: stop keeping everything in your head, capture it somewhere external, connect ideas, search through them when needed and retrieve what’s relevant.
Many people, myself included, have adopted these tools and some of the principles that promoted their best and most efficient use. But, nonetheless many of us found usefulness in finding again stuff we had forgotten about long ago, or similarities between two things we thought were alien to each other, these systems didn’t get better, smarter or more intelligent as we fed and saved in them more valuable content. You could search and retrieve, but you couldn’t really synthesize concepts across sources or surface connections between a paper you read in 2023 and a case study you ingested last week.
But last month (April 2026), Andrej Karpathy (co-founder of OpenAI and former Director of AI at Tesla) published a short Github gist describing a pattern he called an LLM wiki.
Karpathy described the wiki as a collection of markdown files: summary pages, concept pages, entity pages, comparison tables, all interlinked with wiki-style links.
When you add a new document, the AI doesn’t restart. It reads what’s new, updates existing pages, creates new ones where needed, flags contradictions. Thus, with this approach, the wiki becomes the accumulated output of all that processing. It persists. It grows. It improves.
The idea may sound simple, but it is actually a deep conceptual shift.
Instead of making an AI assistant re-read your raw documents every time you ask a question (which is what most AI-powered knowledge tools do, through a technique called Retrieval-Augmented Generation, or RAG), Karpathy proposed compiling your knowledge first.
Use an LLM to read your sources and synthesize them into a persistent, structured wiki: interlinked pages covering entities, concepts, summaries, comparisons. Then run all your queries against that compiled artifact, not against the raw pile of PDFs and notes.
That difference has strong, impactful consequences.
With RAG, every query starts from zero. The AI searches your documents, builds its own context, produces a relevant answer, and then forgets it. Nothing stays. Nothing accumulates or builds something bigger.
When you use an LLM wiki, all that knowledge compounds.
Every new source you add updates the wiki rather than expanding the pile of documents. The overall structure gets richer and more nuanced. The connections get denser. Answers get significantly better because now they come from a system that has a sense-making mission in its DNA.
The only problem, for all of us who are not coders or tech-experts is that Karpathy transparently shared his idea, but left it to us to implement.
The Curator App
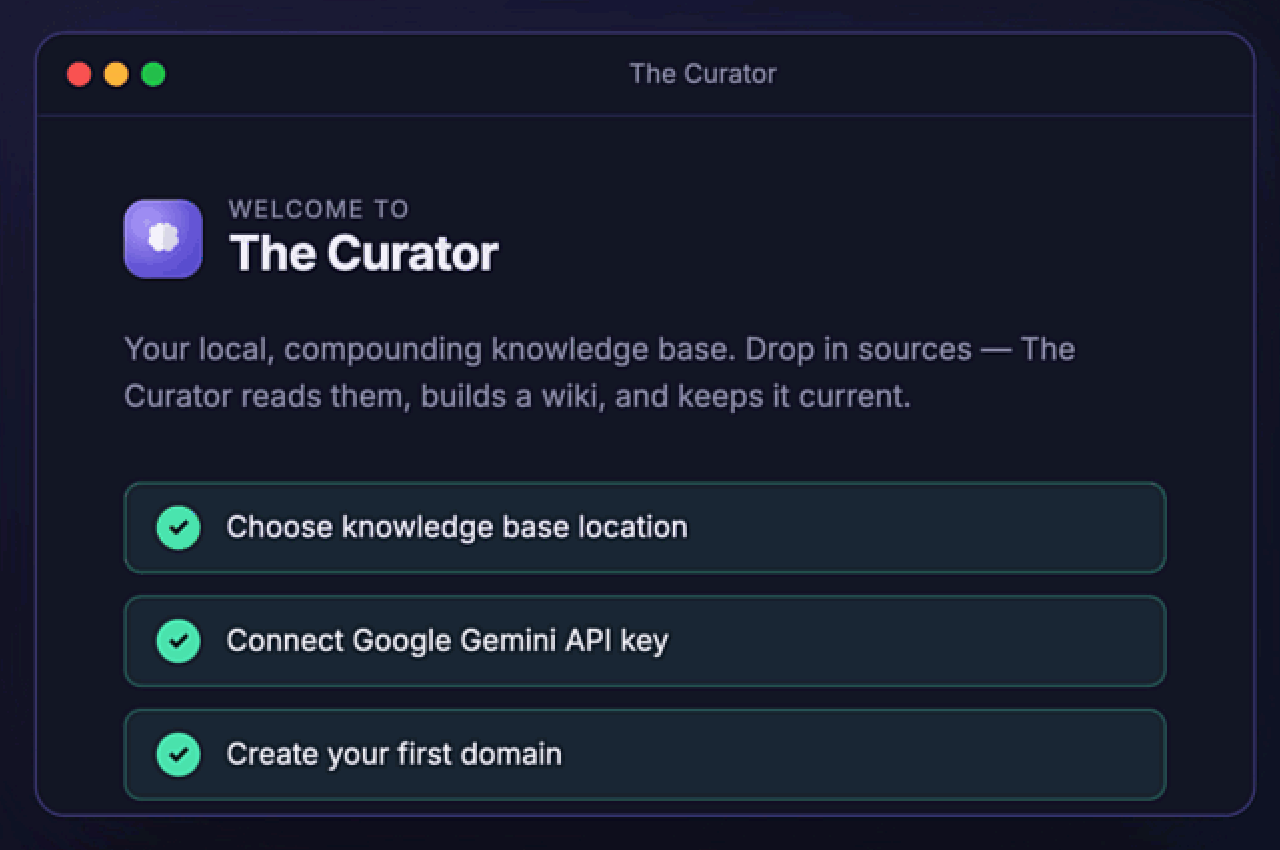
Enter Dr. Tali Režun, a Slovenian/Jordanian entrepreneur-professor, philosopher-builder, who took Karpathy’s advice and turned it into an open-source working application that almost anyone can start using today.
The Curator, an open-source tool published on GitHub, implements the Karpathy LLM-wiki concept for people who are not developers and have no interest in configuring LLM pipelines.
Think of it as a personal Wikipedia, but with the additional capabilities of writing, maintaining, and expanding itself, while you play as the director / editor-in-chief rather than the classical author / collector.
What The Curator System Actually Does

The Curator is a local desktop application. It runs on your machine. You install it, connect it to an AI provider (Google’s Gemini 2.5 Flash is the recommended option, or you can also use Claude - as I did - by buying a small amount of credits), and you start feeding it your materials: PDFs, articles, research papers, notes, transcripts, whatever you’ve been saving in your area of expertise.
Now, this is what happens when you do so: When you ingest a document, The Curator doesn’t just store it. It processes it. Through AI it reads the source and breaks it down into three types of nodes:
Entities (people, companies, tools, organizations),
Concepts (ideas, frameworks, methodologies, techniques), and
Summaries (the narrative of what the source actually argues).
These, also referred as nodes, are stored as plain markdown files with structured metadata: no proprietary database, no lock-in, and they are fully readable by any text editor, archivable and portable.
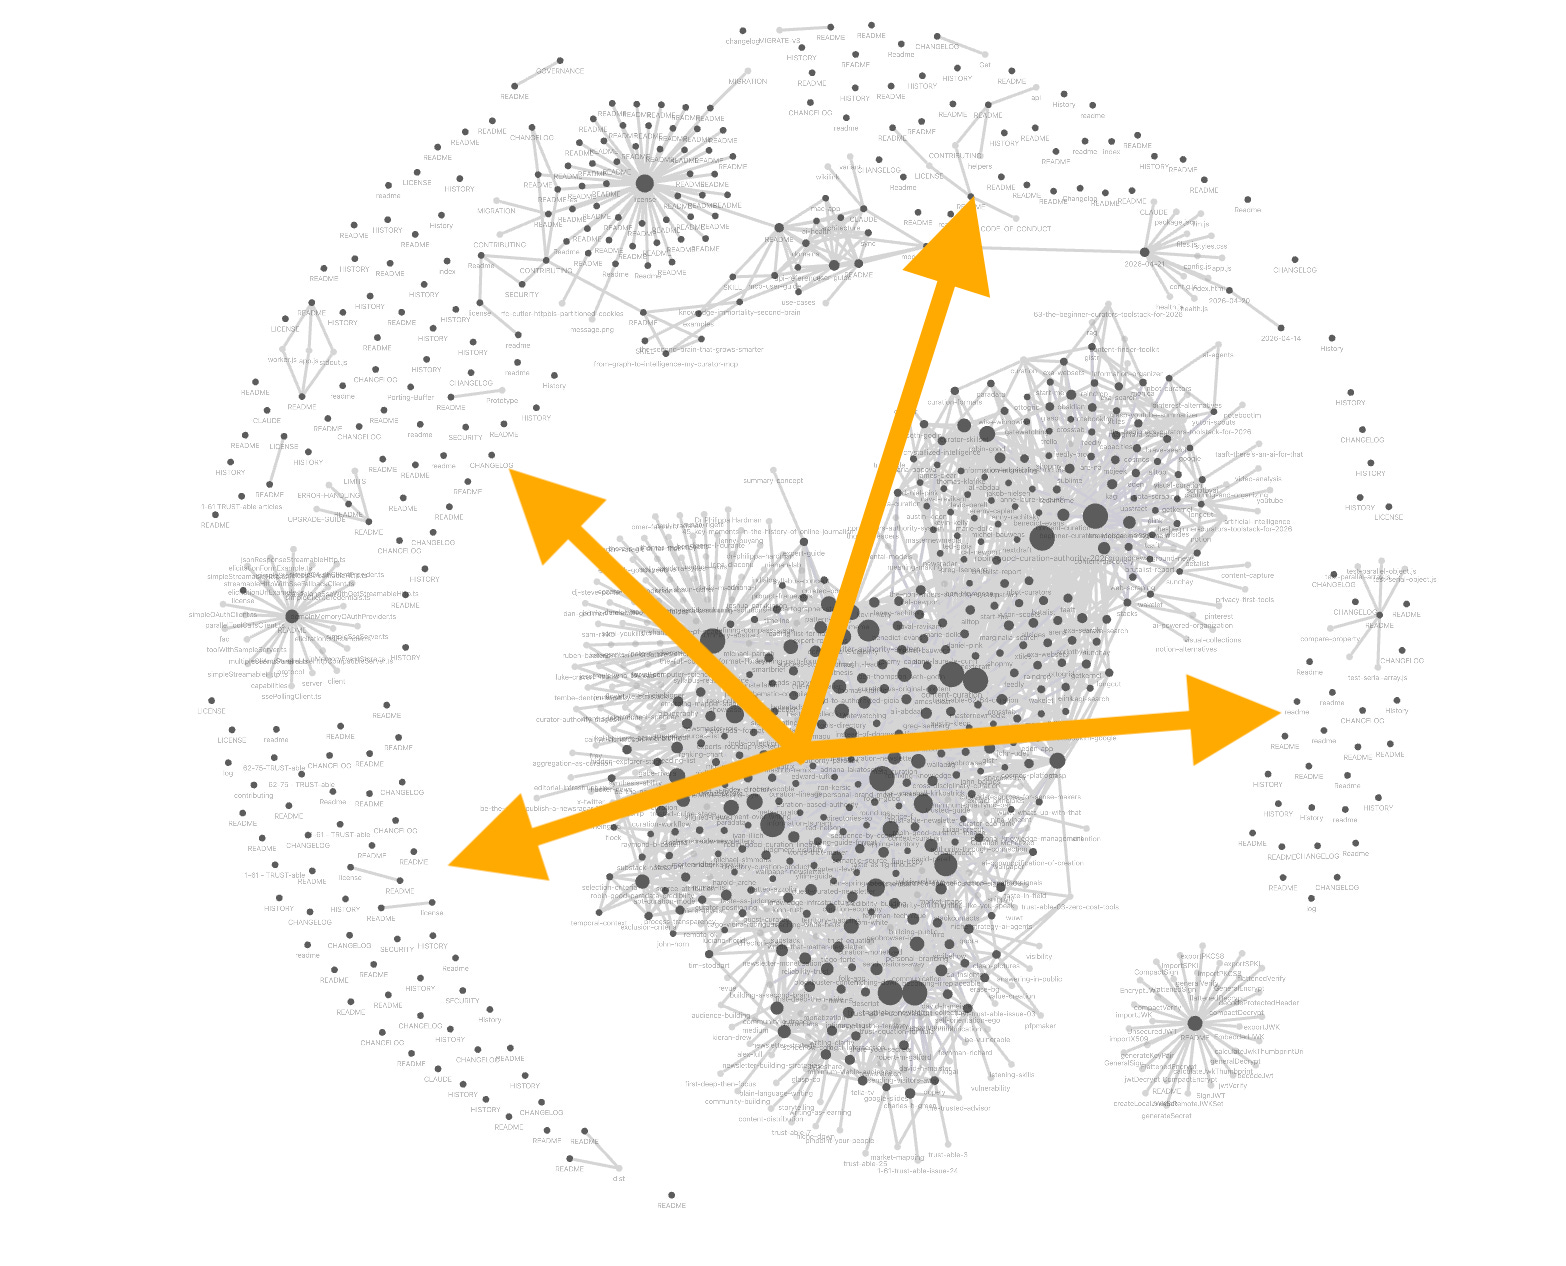
More importantly, these nodes link to each other. Add ten sources about “trust” or “credibility” or “knowledge management” and the system builds an information web: concepts appear in multiple summaries, entities connect across papers, competing ideas get mapped against each other.
Your second brain has now transformed itself into a knowledge graph: a visual network of objects, events, situations or concepts, highlighting the relationships between them.
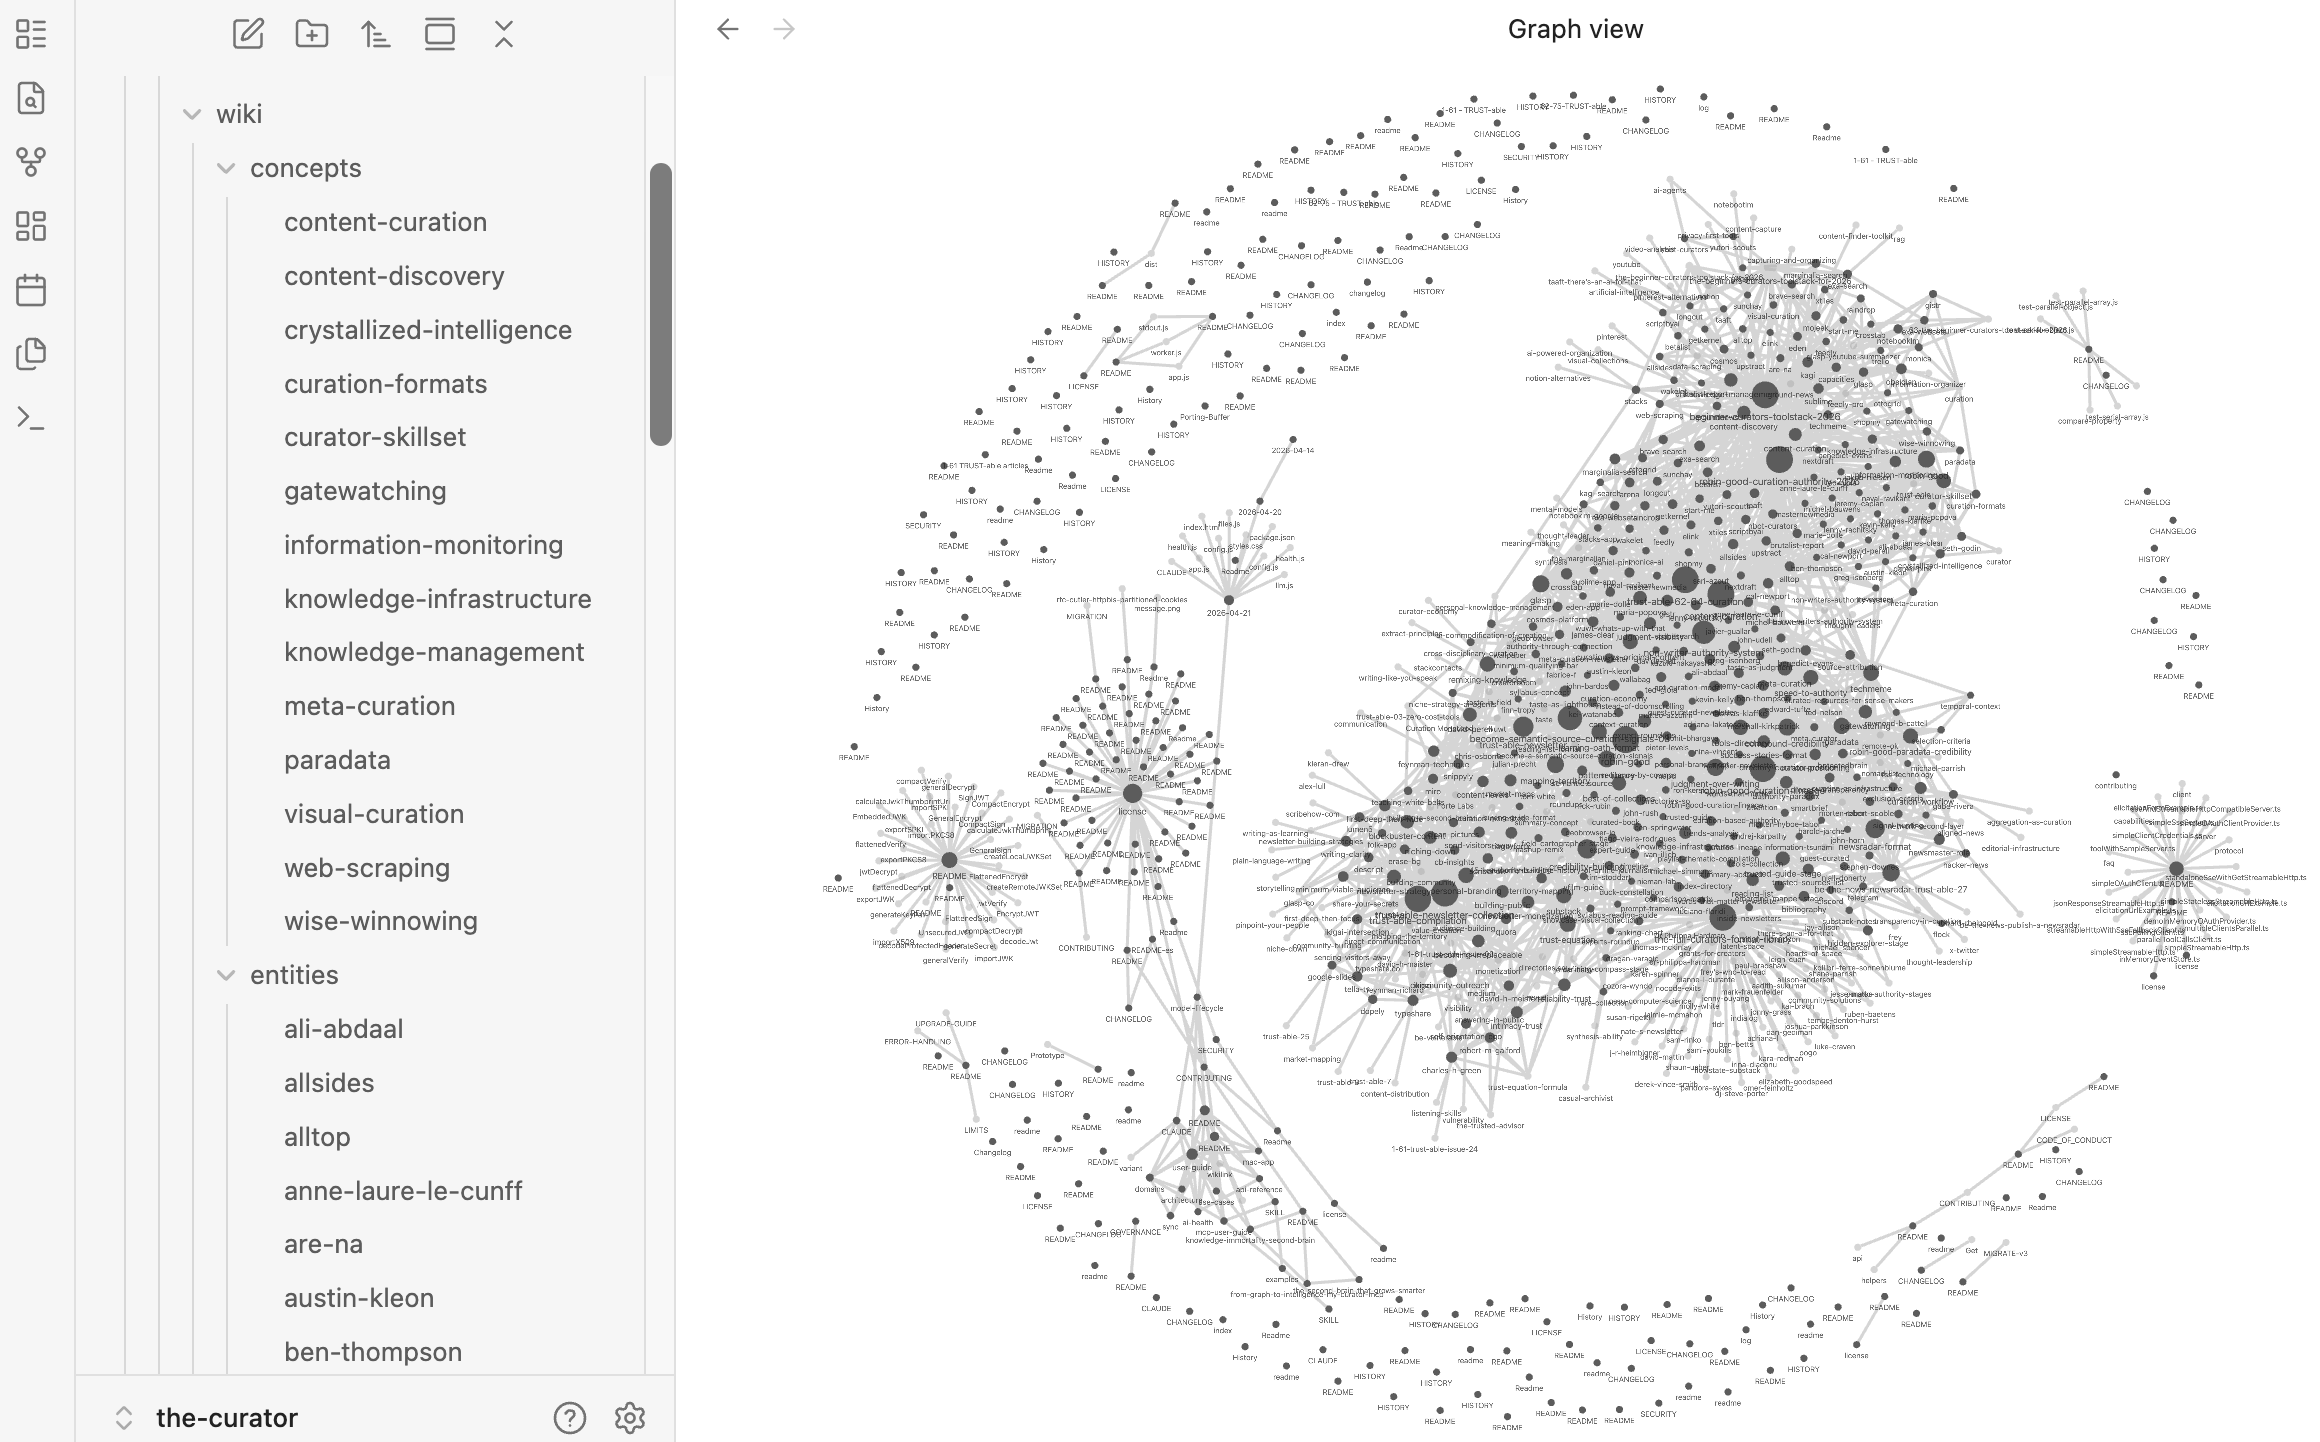
You can visualize this knowledge graph in Obsidian (a free, open-source, widely-used second-brain tool and markdown editor) where nodes are color-coded by type and you can navigate their connections visually.
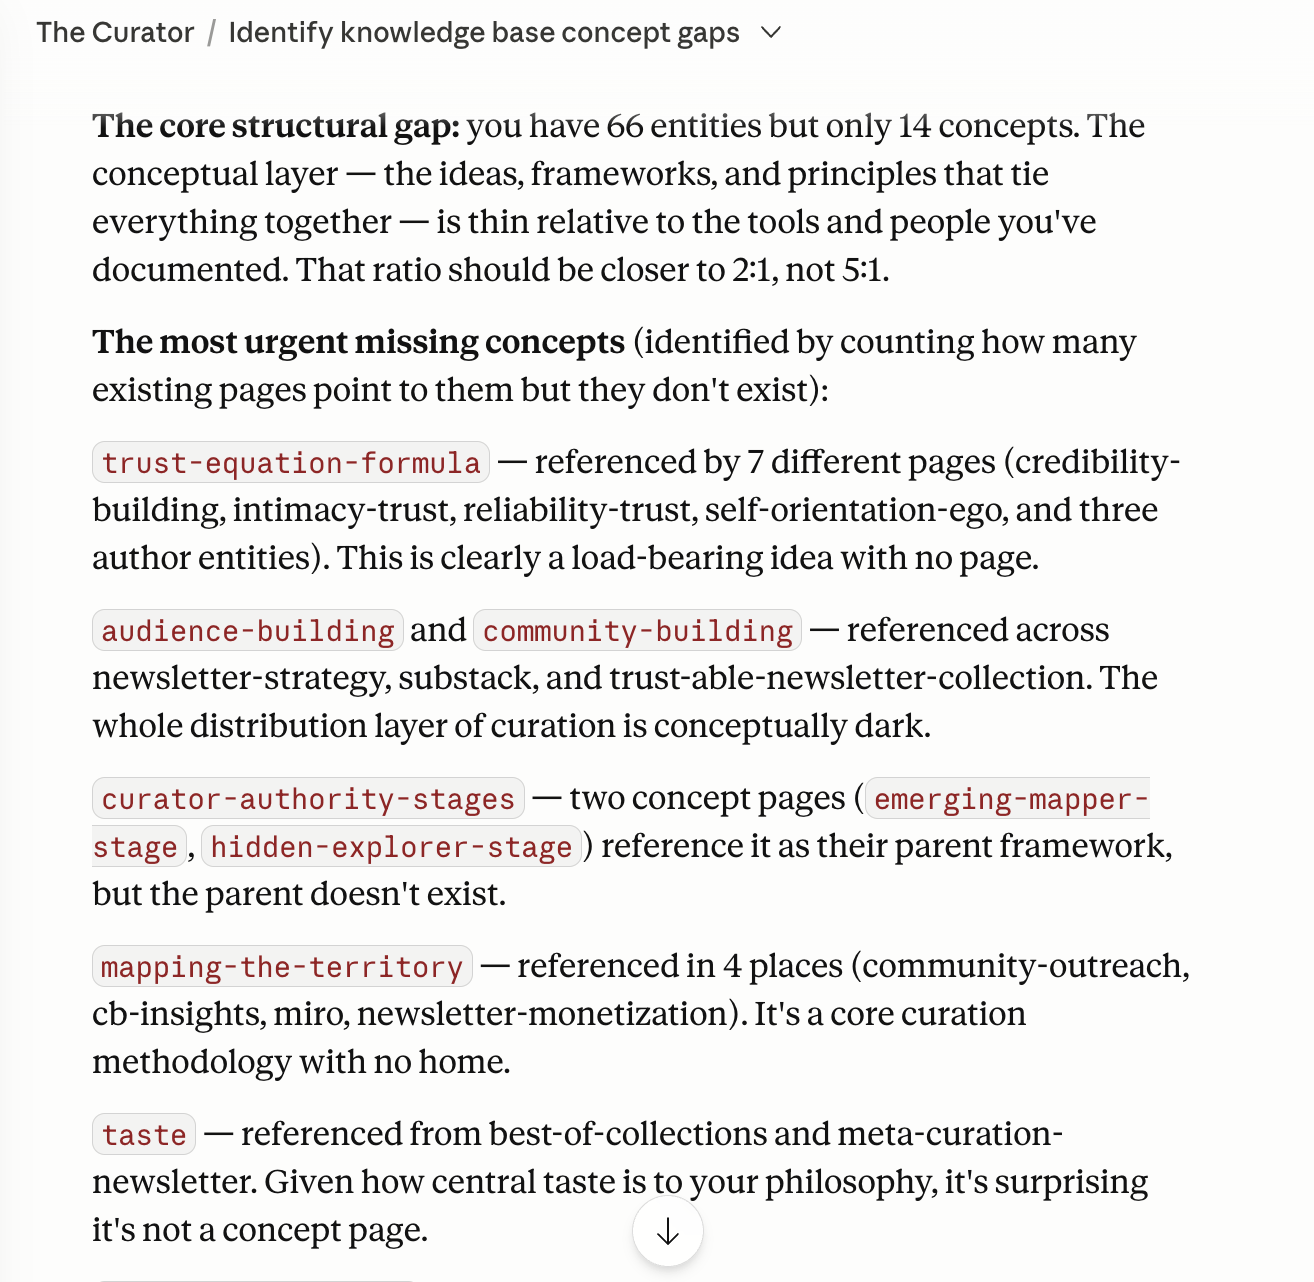
One thing that's genuinely valuable and unique: through this approach you can far more easily identify “structural gaps” in any knowledge domain: you can see which concepts are well-connected and which are not, which entities keep appearing across sources and which are mentioned once and dropped.
But the real interaction with The Curator happens through chat.
The Curator allows you to ask questions against your compiled knowledge base (”What are the main critiques of RAG-based systems?” or “How do the frameworks I’ve studied compare on the question of knowledge decay?”) and the system answers from its structured, internally-built understanding, not from a basic search through your document and files. The Curator traces claims to sources, flags sources that contradict each other, and can actually follow a concept and its relevance across your entire knowledge base.
But the feature that makes The Curator impossible not to look into is: conversations you have via the AI chat with the knowledge base can be permanently saved back into the wiki. Thus, when an exchange you have with the system produces new information and facts, interesting insights or new perspectives, you can commit that content as a new information element inside the knowledge base.
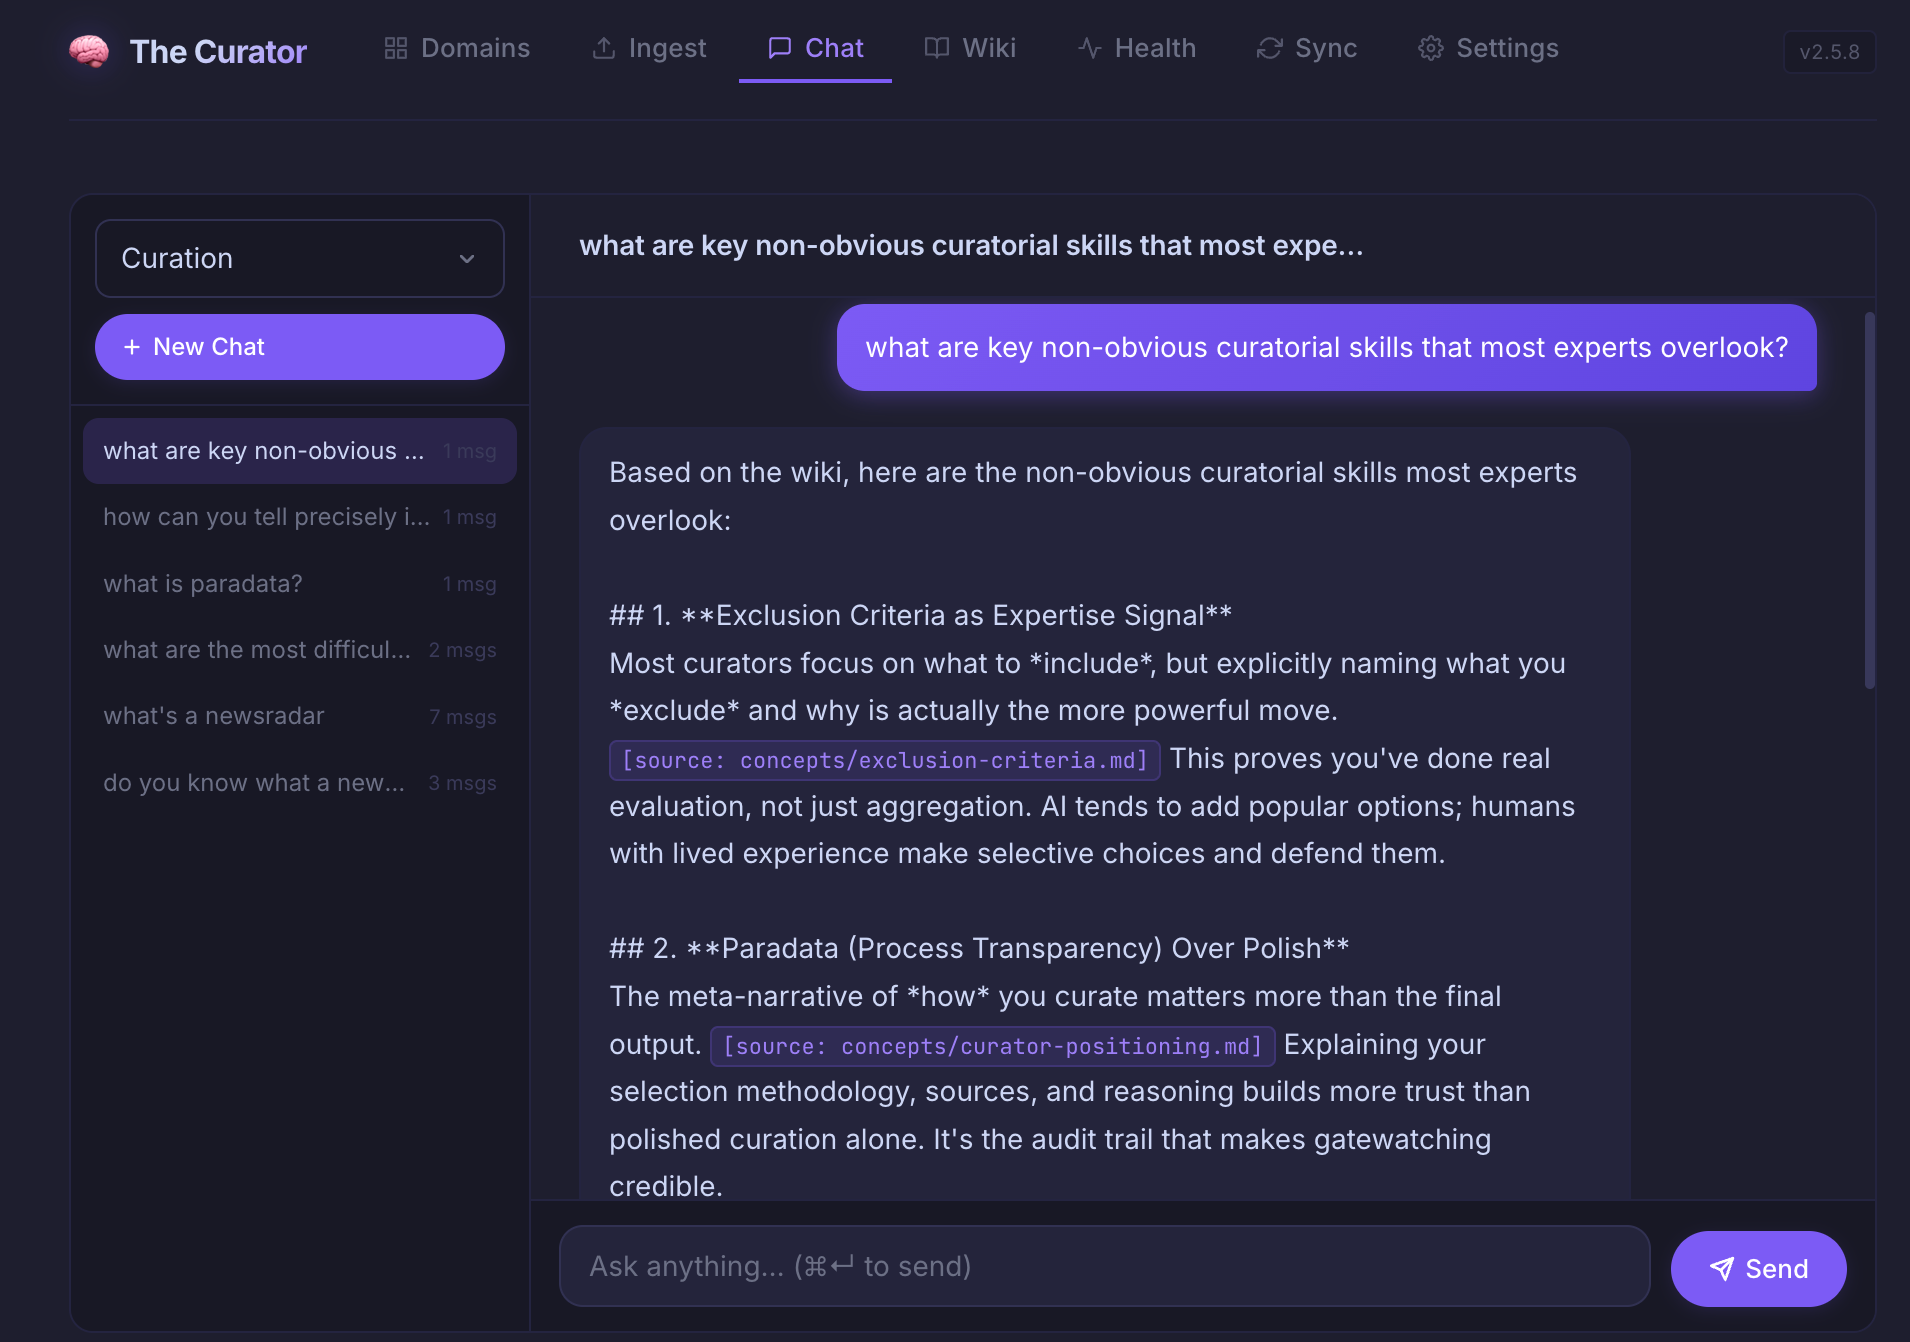
In this way, the LLM-wiki grows not just from what you’ve read and ingested in the system but also from what you’ve thought, researched, discussed and analyzed. Your own reasoning becomes integral part of the knowledge base structure.
But there are three more important features to notice in how the Curator system works and in what it enables.
a) Health Checks
In Karpathy's paradigm, the wiki is not just a mirror of the source documents you have ingested. The wiki is the primary artifact. The source documents are inputs but the wiki is the compiled intelligence you actually work from.
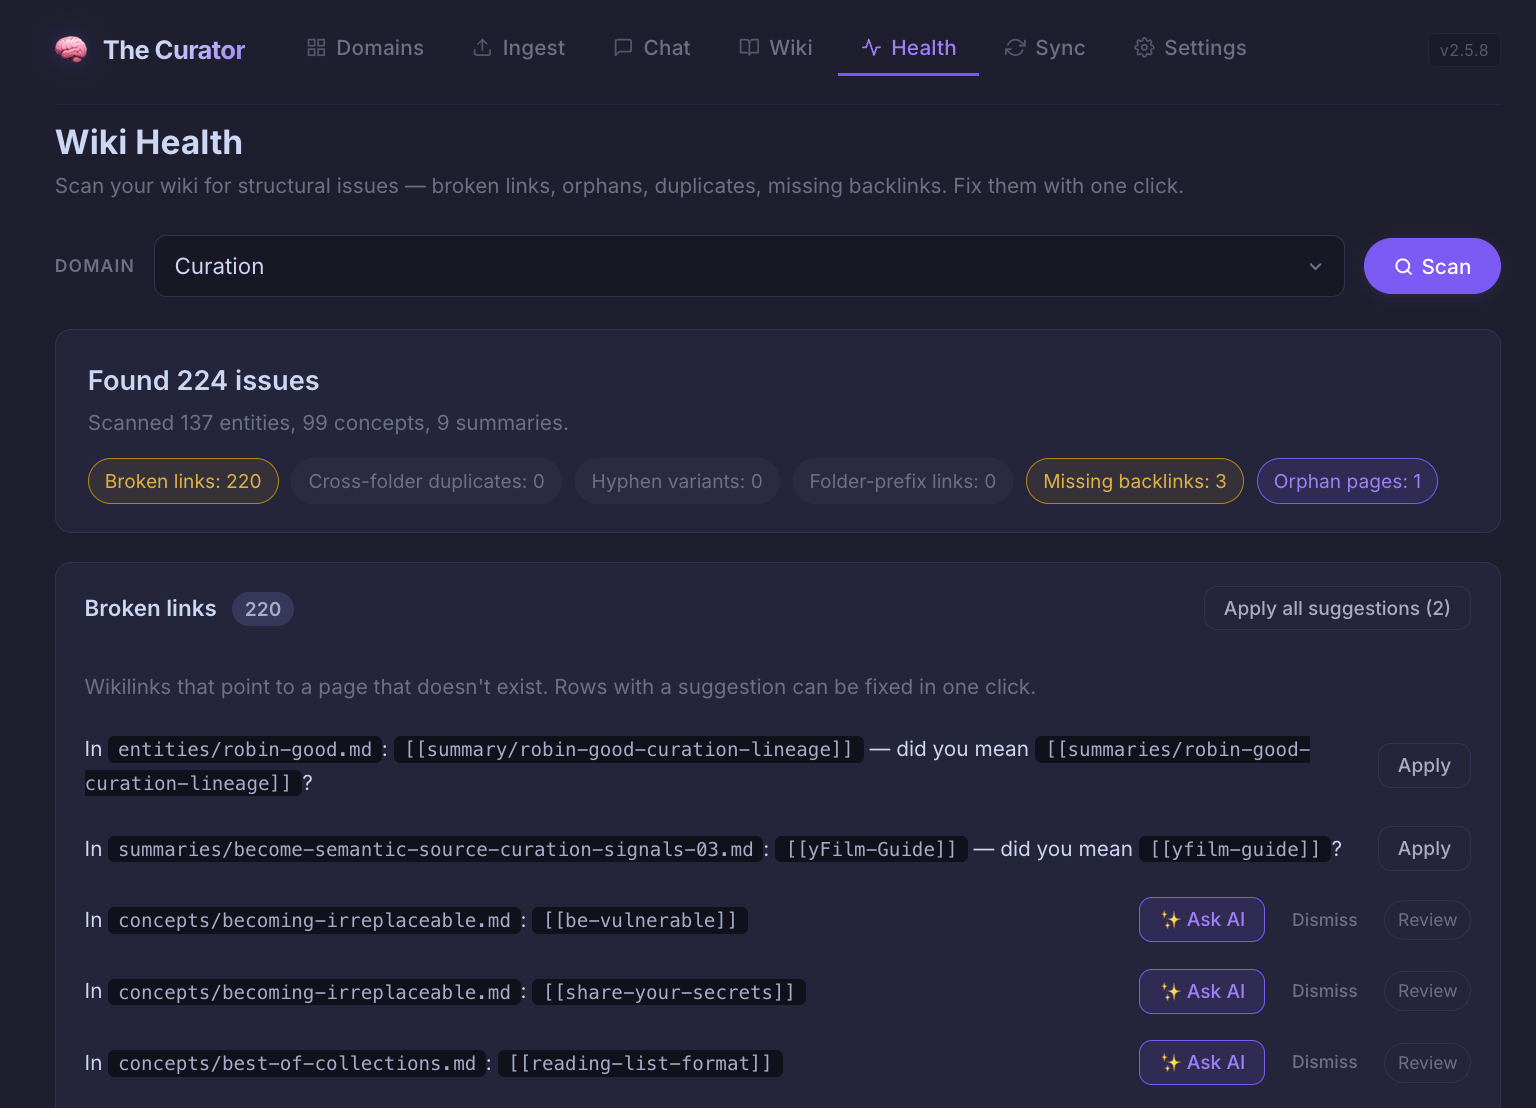
In this context, structural integrity of the wiki, becomes an important element to consider. In fact, while in a traditional second-brains or other knowledge system, broken links are an inconvenience. Here, they become a failure of the compounding mechanism itself. Orphaned nodes never get surfaced in synthesis. Semantic duplicates, where the same concept has been stored under slightly different names across separate ingestion sessions, split a single idea in two, preventing it from ever being properly cross-referenced. Broken internal links sever chains of reasoning mid-graph. And all of these obviously matter more the larger your knowledge base grows.
The problem isn't just that your knowledge base gets messier. But that, over time, the messiness compounds itself, and you have no way of easily seeing it. Health checks are the mechanism that maintains the integrity of the wiki artifact that the whole system depends on.
For this very purpose The Curator includes a Wiki Health scan that identifies these issues automatically and surfaces them for repair. You can fix them manually through the app, one by one or - by leveraging the MCP bridge (explained below) - route the health scan output directly to Claude Opus or another frontier-level AI, by describing your repair criteria, and let that AI resolve structural issues across the entire graph in a single session.
b) Obsidian as the knowledge base editor
Obsidian is where The Curator sends its output — a free markdown editor that renders your knowledge graph visually, with nodes color-coded by type.
But what it’s really worth noticing is what this means in practice. Because every node in your knowledge base is a plain .md markdown file, Obsidian is not just a read-only visualization tool. It’s a full editor.
You can open any page in your knowledge base, read it, modify it, add to it, link it manually to other nodes, or delete it. The knowledge graph view updates to reflect your edits in real time.
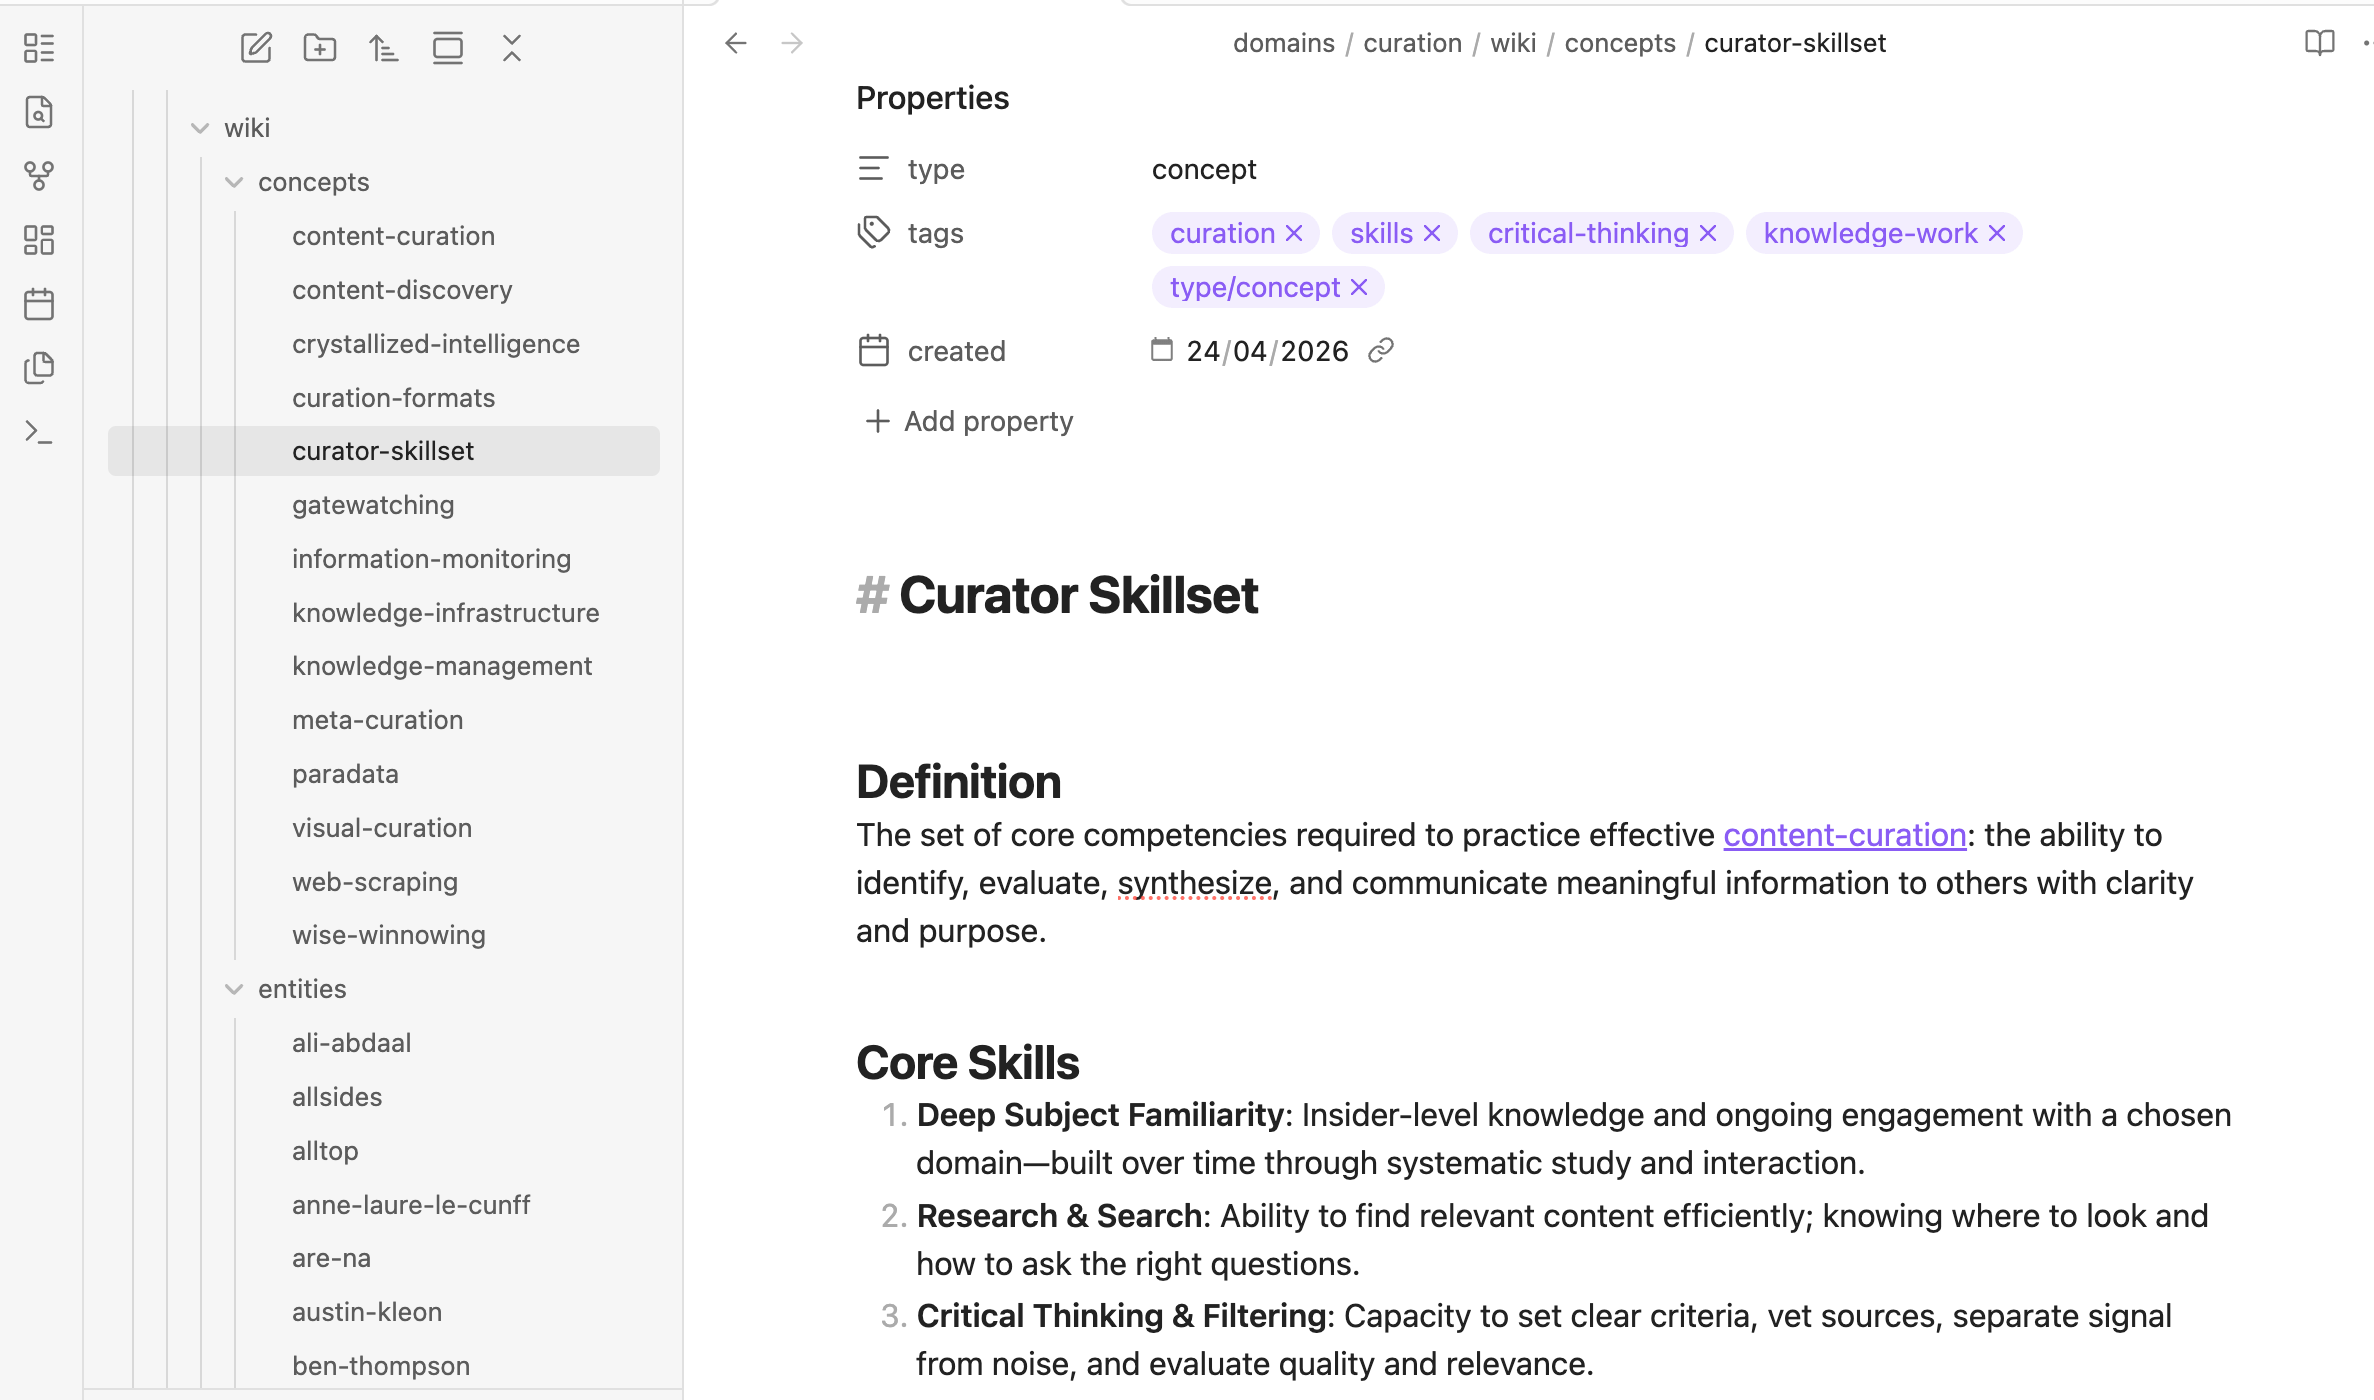
For an expert who wants direct hands-on access to their knowledge base without going through a chat interface, this is a genuinely useful alternative entry point and a reminder that plain markdown files mean your knowledge lives entirely somewhere you can directly control.
c) The GitHub Sync
Because the entire knowledge base is plain markdown files, syncing it to a private GitHub repository is straightforward and built into The Curator.
This gives you automatic versioning, a full history of how your knowledge base has evolved, and access from any machine.
Your compiled intelligence travels with you — and if anything ever goes wrong, you can roll back to any previous state.
The Cherry On Top: The MCP Bridge
But there’s more and here things get even more exciting.
The Curator system, comes equipped with a so-called MCP bridge (a technical layer that lets Claude Desktop connect directly to your knowledge base) means your compiled knowledge can be used as a live data source by an AI agent, not just by you. The knowledge graph becomes something you can put to work to create tools and access points that make that knowledge useful and actionable for others.
Like: You can build domain-specific query systems on top of it. For example a research assistant that only draws from your curated sources, or a Q&A interface trained on your specific curation choices, or surfacing answers none of the general-purpose AI tools can match because they don’t have access to your proprietary knowledge graph. And so on.
Your knowledge base stops being something only you can access and becomes knowledge infrastructure you can actually deploy.
Through the Curator MCP you can query across topics / domains, retrieve connected nodes, search semantically, surface backlinks.
If you’re already using Claude Desktop as a working environment, this integration is not theoretical. You add it once and your knowledge base becomes a live layer behind everything you’re doing.
This is what “knowledge infrastructure” means in practice.
A proprietary structured intelligence that sits behind your work and compounds with every source you add.
Honest Caveats
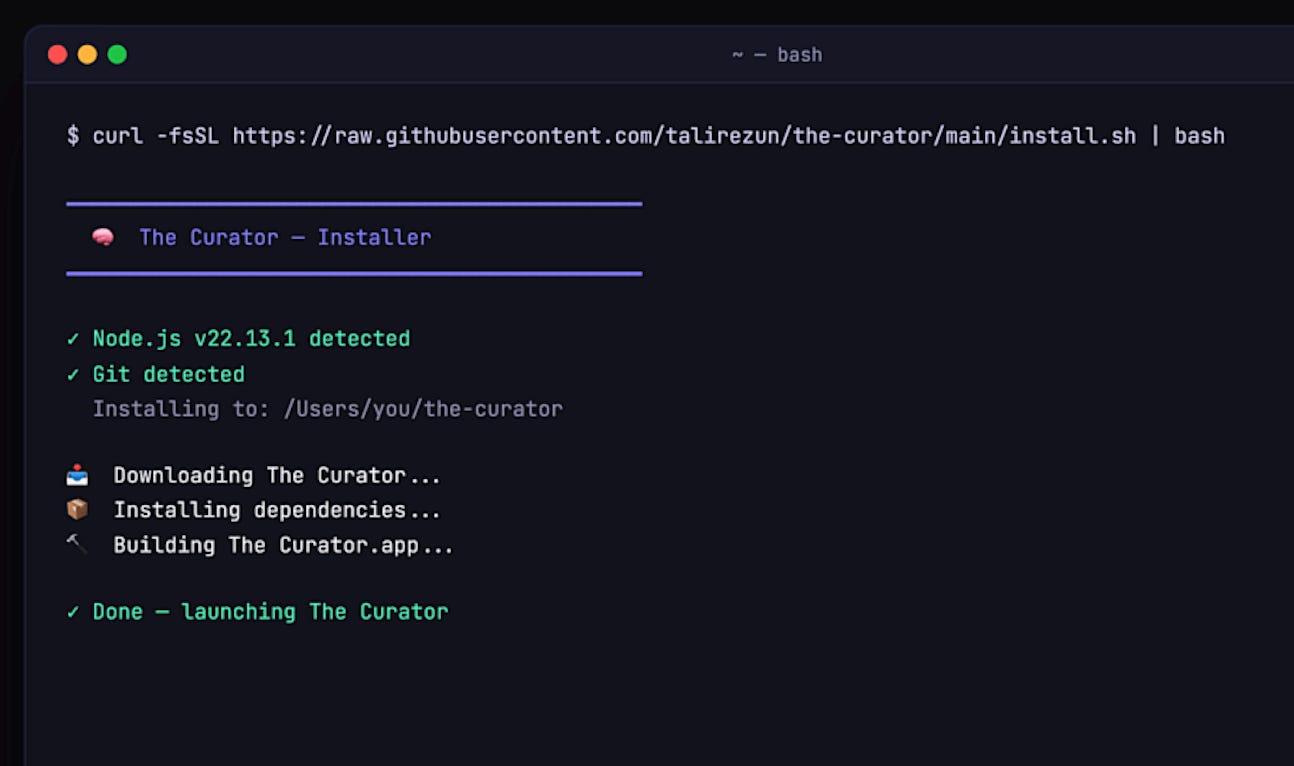
Warning: The Curator is early-stage software. I have downloaded it, installed and configured it all by myself by simply following the available instructions, but this process is not like downloading and installing a normal app.
For example: the installation requires Node.js and npm, which is not stuff that I am familiar with. Even so, Dr. Ražun has done his best to make his system accessible to non-technical people, you need to have some patience and willingness to do things you may not be too familiar with. In my case, when I didn’t know how to execute some of the installation steps, I simply asked Claude to help me, and in less than one hour I was able to have The Curator properly configured and running.
Also: The authority-building argument made here is largely my interpretation of what this kind of tool enables while the creator’s own framing is more technical.
Using Anthropic’s Claude API instead of the free Gemini option does cost more, but for personal reasons I did not want to open a new line of payments with Google. Dr Režun says that using Claude can cost up to ten times more than using Gemini. So, if you can use Gemini, start from there, and then if you are unsatisfied or have reasons not to use the Google AI, move on to buy some API credits from Claude Console.
How To Best Use It
This is how I suggest you frame and use The Curator in your own work:
The most useful approach for a writer is a hybrid that takes the best of both systems.
Use Karpathy’s architecture for the raw and mapping layers: let the LLM build the interconnection graph, surface gaps, maintain the index, identify unexpected cross-source connections. This is domain scaffolding, and the LLM does it better than any human could.
But keep the synthesis layer human.
When the LLM shows you that two ideas are structurally connected, don’t read its synthesis article. Write your own.
Take the connection it has surfaced and struggle with it in your own words. What does this connection actually mean? Does it hold up? Where does it break down? What would it imply if it were true? This is where your voice and your argument live.
In this configuration, the wiki is not the output of your thinking. It is the well-organized input to it. The scaffolding, not the building. The map of the territory you’re about to enter on foot, knowing the map is not the same as walking the ground.
…
The synthesis is: use the machine to build the map, then insist on walking the territory yourself. Let the LLM handle the compilation. Reserve the thinking for yourself.
Source: Extended_Brain - “The Wiki That Writes Itself”
The window for early-adopter advantage in tooling like this is always shorter than it looks.
An expert who starts building a private knowledge infrastructure today (adding sources methodically, letting the knowledge graph develop, using it to deepen the quality of what they produce and publish) will not have the same capability in twelve months as someone starting from zero. The compounding effect is real. That’s the whole point of the design.
The knowledge base you’re not building right now is the authority gap you’ll notice later.
The Curator is a serious implementation of Karpathy’s LLM-wiki concept, built by someone who clearly understands both the architecture and the knowledge management problem it’s addressing.
Where To Start
The Curator
(open-source, free): github.com/talirezun/the-curatorKarpathy’s original LLM Wiki concept: gist.github.com/karpathy/442a6bf555914893e9891c11519de94f
Quick Start Installation Guide
github.com/talirezun/the-curator#quick-startUser Guide
github.com/talirezun/the-curator/blob/main/docs/user-guide.md
Paradata
Intent: I wrote this because on April 23rd I discovered Dr. Tali Režun articles presenting The Curator app and I immediately this was highly relevant to my focus area, interests and to my readers: Experts working to increase their authority and credibility online not by way of producing more content but by creating sense-making tools, resources and knowledge infrastructures.
Process: I read thoroughly Karpathy’s LLM wiki gist and all of the articles from Dr. Tali Režun that were available. I downloaded and installed The Curator app, following the instructions available in the official documentation and asking a little help from Claude whenever I bumped into something I didn’t know how to do. I then ingested 7-8 PDFs of articles I had written on curation, to see the system at work on a topic that I am very familiar with. Right after having tested all of The Curator basic features, I decided not to go deeper, but to draft immediately this article.
Realizations: I feel the need for much more in depth testing of The Curator with a much larger set of documents. I want to see in practice how good it gets and what kind of practical uses I really have for it. I am planning a second instalment of this article, especially if this first report will prove that there is strong interest and desire to learn more about this topic.
Timing: Reading and studying the LLM-wiki concept took me 3-4 hours. Installing The Curator took under an hour, and ingesting and processing a first batch of documents added another hour-plus on top of that. Testing all the main features, the MCP bridge, and the Obsidian integration took 2 more hours. Writing down what I wanted to say and building the full outline took another 2 solid hours. Polishing the text, adding images, captions, resources, and links took 3 more hours. Then 1 hour to land on the final title and subtitle, plus another to handle formatting and catch small errors. Total: roughly 13.5 hours.
Tools: The most useful tool during the initial study phase was WUWT, a Chrome extension I’m relying on more and more. It does deep analysis on any text, PDF, document, or video, surfacing concepts, ideas, connections, risks, and opportunities that you won’t catch on a first pass. For drafting, I used Google Docs and Claude Cowork. Claude helped me organize all the material into a structure that made sense, and worked through some of the core concepts until they were clear and readable. The text, words, and sentence structures are all mine.
Suggested Readings:
The Second Brain That Grows Smarter and Lives on your Computer - by Dr. Tali Režun
Building Knowledge Immortality Through the Second Brain Architecture and The Curator App - by Dr. Tali Režun
From Graph to Intelligence: The My Curator MCP and the Art of Querying Your Second Brain - by Dr. Tali Režun
What I Can Do For You
I help experts and consultants building a new online career gain the authority, credibility, and visibility they initially lack.
I do this by teaching them how to become top trusted curators in their area of expertise.
For this purpose I’ve created a free, focused 55-minute video workshop that walks you through:
Why curated content formats are so useful to build credibility and authority
When to use them and what requirements they have
An updated list of real-world examples of curated formats at work
The specific tools you need to curate
The actual key steps that transform researching and writing into curation
The 11 typical mistakes novice curators make
One-to-One Audit & Strategic Advice
For experts and consultants looking for ways to:
a) Create Value and Build Trust for Non-Writers (Curation)
I help you identify and master your own personal ways to gain authority and value by curating insights, research, news, resources and tools in your field of interest.
b) Improve Credibility and Trust
I review your content, positioning and goals to identify best editorial strategies to build trust and credibility around your focus.
c) Positioning and Personal Branding
I analyze your market positioning to identify key strengths and weaknesses. I help you redefine a strategy to differentiate yourself from the competition while increasing the practical value you bring to your readers.
Available in two tiers: a) for those just starting and b) for those who have been publishing for more than a year, but are not seeing results.
Follow a path with a heart.
The time is now.

From Koh Samui (TH)
Robin Good
Thank you for sharing this. Excited to try The Curator!
Wonderful article, thank you for sharing such valuable resource.